How I Fixed LCP, TBT, and 1,400 KiB of Wrong Images on a WordPress LiteSpeed Site (And What Broke Along the Way)
Rantideb Howlader••19 min read•
By Rantideb Howlader
I run studyinfo.net as a side project - an educational site about universities and scholarships, built on WordPress and hosted on Hostinger's LiteSpeed tier. My day job is SRE work.
In July 2026 I opened PSI for the first time in months and saw a desktop score of 78. Two open violations:
- LCP > 1.0s (sitting at 2.4s - the main image was being fetched at 1,200px wide to fill a 270px card)
- TBT > 0ms (460ms - the main thread locked solid for nearly half a second on every load because of one wrong toggle)
SLO is a Service Level Objective - a threshold I set before touching anything, so I have a definition of done that is not just the number went up. LCP under 1.0s and TBT at 0ms are aggressive targets.
Both are achievable on a clean LiteSpeed stack.
I fixed both over a weekend using only LiteSpeed Cache v7.8.1 and two WPCode PHP snippets, without touching a single core file, theme file, or plugin directly. Then I broke it.
The score dropped to 74 overnight because of a LiteSpeed preset system I did not know existed. That part is in here too.
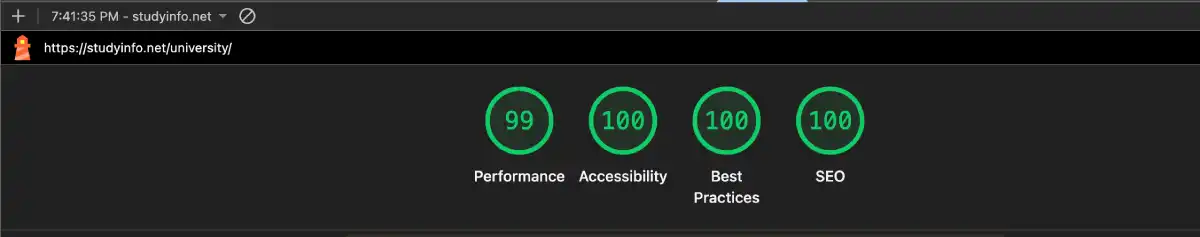
Final result, verified across three consecutive PSI runs:
| Metric | Before | After |
|---|---|---|
| Performance | 78 | 99 |
| FCP | 1.2s | 0.4s |
| LCP | 2.4s | 0.8s |
| TBT | 460ms | 0ms |
| CLS | 0.14 | 0.054 |
| Speed Index | 4.1s | 2.5s |
The Audit Journey
flowchart TB
    Start(["📊 Initial State (PSI: 78)
    LCP: 2.4s | TBT: 460ms"]) --> Phase1

    subgraph Phase 1: Critical Rendering Path
        direction TB
        Phase1[Identify Render-Blockers] --> JQ[jQuery blocking 1,100ms]
        JQ --> Fix1(LiteSpeed: Defer jQuery)
        Phase1 --> Dash[Unused Dashicons]
        Dash --> Fix2(WPCode: Dequeue Dashicons)
        Fix1 & Fix2 --> Result1{"Score: ~90
        FCP: 0.5s"}
    end

    Result1 --> Phase2

    subgraph Phase 2: The JS Combine Regression
        direction TB
        Phase2[Enable JS Combine] --> Issue2[All JS bundled into single 340KB file]
        Issue2 --> Issue3[Destroys HTTP/3 Multiplexing]
        Issue3 --> TBTSpike[Main Thread locks for 460ms]
        TBTSpike --> Fix3(Revert: JS Combine OFF)
        Fix3 --> Result2{"Score: ~95
        TBT: 0ms"}
    end

    Result2 --> Phase3

    subgraph Phase 3: Hidden Blockers & Payload
        direction TB
        Phase3[Analyze Remaining LCP] --> Font[Inter Font invisible for 1.48s]
        Font --> Fix4(LiteSpeed: font-display: swap)
        Phase3 --> Img[1200px images in 270px cards]
        Img --> Fix5(WPCode: Rewrite sizes attribute to 300px)
        Fix4 --> Result3[LCP drops to 1.1s]
        Fix5 --> Result4[Image Payload drops by 1,400 KiB]
        Result3 & Result4 --> Final{"Score: 99
        LCP: 0.8s"}
    end

    Final --> Success(["🏆 Final State (PSI: 99)
    All SLOs Met"])
Why LiteSpeed Cache Behaves Differently on LiteSpeed Web Server
The site runs on Hostinger's cloud hosting tier, which uses LiteSpeed Web Server - not Apache, not nginx. That is not a marketing distinction.
It changes which tools are actually worth using.
LiteSpeed Cache for WordPress integrates directly with the server through a shared memory API. When it optimizes CSS and JavaScript, that processing happens at the server layer before the response leaves the origin - not in PHP, not in the browser.
And when it serves pages, it does so over HTTP/3 (QUIC) natively, which LiteSpeed Web Server has supported since before Nginx had a stable implementation.
That last detail - HTTP/3 - turned out to be directly relevant to the biggest mistake I made.
I ran every change in isolation. One change, purge all cache layers, wait 90 seconds, run PSI three times, take the median.
If you make three changes and the score improves, you have learned nothing you can act on when it regresses - and it will regress.
Deferring jQuery Fixed 1,100ms - Then JS Combine Spiked TBT to 460ms
The first PSI audit flagged jquery.min.js as a render-blocking resource responsible for roughly 1,100ms of delay. The mechanism is not subtle: jQuery was enqueued in <head> without defer or async.
When the browser's HTML parser hits a synchronous <script> tag, it stops. Everything stops.
It fetches the file, waits for the network, hands the bytes to V8, compiles and executes the script, and only then resumes parsing the DOM. On a cold load with no cache primed, that is an entire network round-trip plus compile time, all before a single pixel paints.
The fix in LiteSpeed Cache is under Page Optimization > JS Settings: enable Defer JS, and separately enable Defer jQuery. The two toggles exist because jQuery is a special case.
WordPress plugins routinely inject inline <script> blocks that call jQuery() directly, assuming it already exists in the global scope. If you just add async to jquery.min.js, those inline callers execute before jQuery loads and throw reference errors.
LiteSpeed's implementation handles this by injecting a shim that queues jQuery() calls and flushes them after the deferred file executes. The plugins keep working.
The parser keeps moving.
FCP dropped from 1.2s to 0.5s. LCP moved from 2.4s to around 1.6s. I was satisfied, so I immediately made things worse.
I enabled JS Combine.
The reasoning seemed sound: fewer HTTP requests, less round-trip overhead. That logic is correct for HTTP/1.1, where each request requires its own TCP connection.
In 2014 this was real advice. studyinfo.net runs on HTTP/3.
Under QUIC, every request shares a single multiplexed UDP connection. There is no connection overhead to amortize.
The entire performance argument for JavaScript bundling on this stack does not exist.
What JS Combine actually produced: a single 340KB bundle assembled from 14 individual files. The browser received it and had to compile the entire 340KB on the main thread before executing any of it.
V8's streaming compilation - which lets the engine compile file 1 while file 2 is still downloading - only works when files arrive as separate streams. A bundle is one stream with no interleaving opportunity.
I opened Chrome DevTools > Performance, recorded a load, and saw a solid yellow Evaluate Script block spanning 460ms. That is 460 milliseconds where the main thread cannot respond to any user input.
That is exactly what PSI reported as TBT.
JS Combine: off. TBT: 0ms.
I want to be direct about this because I see it recommended constantly: on any site running HTTP/2 or HTTP/3, JavaScript bundling is not an optimization. It moves overhead from the network layer - which is already efficient - to the main thread, which is the bottleneck you are actually trying to protect.
Measure before you enable it. If you are on LiteSpeed, you are almost certainly on HTTP/3.
WordPress sizes="100vw" Was Sending the Wrong Image - 1,400 KiB Per Page Load
With TBT resolved, the next PSI run surfaced an image sizing warning that I initially dismissed as minor. It was not minor.
It was 1,400 KiB of wasted payload on every archive page.
WordPress generates responsive image markup with srcset - a list of image URLs at different widths - and sizes, which is supposed to tell the browser how wide the image will actually display. The browser uses sizes to decide which srcset candidate to fetch before layout has been computed, during the initial HTML preload scan.
If sizes is wrong, the browser fetches the wrong image and there is no mechanism to correct it mid-load without a second request.
WordPress defaults to sizes="100vw" for post thumbnails. On a 1440px desktop, 100vw means 1440px.
Multiply by the devicePixelRatio of 2 on a retina display and the browser is targeting a 2880px source. The largest available in the srcset is 1200px, so that is what it fetches.
On the homepage and archive pages of studyinfo.net, post thumbnails render inside a two-column card grid. Each card is approximately 270px wide.
The browser was downloading a 1200px image to fill a 270px container on every card, on every page load, for every visitor. With 12 posts per page, that was roughly 1,400 KiB of image data decoded into memory, composited by the GPU, scaled down, and discarded.
I could not edit the theme's functions.php - the theme is version-controlled and updates automatically. Instead, I used WPCode to hook into WordPress's post_thumbnail_html filter:
php
<?php
/**
 * Fix post thumbnail sizes attribute for card grid layouts.
 *
 * WordPress defaults to sizes="100vw", causing the browser to fetch
 * full-width image variants for thumbnails displayed in card grids.
 *
 * On studyinfo.net archive pages, cards render at:
 *   - Mobile (<640px): two-column grid, each card ~50vw
 *   - Tablet and above: ~300px fixed width
 *
 * This filter corrects the hint so the browser selects the 300w srcset
 * candidate instead of 1200w on archive pages.
 *
 * Stored via WPCode - do not duplicate in functions.php.
 *
 * @param string $html              Thumbnail HTML output.
 * @param int    $post_id           Post ID.
 * @param int    $post_thumbnail_id Thumbnail attachment ID.
 * @param string $size              Registered image size name.
 * @param array  $attr             HTML attributes array.
 * @return string Modified thumbnail HTML.
 */
add_filter( 'post_thumbnail_html', function( $html, $post_id, $post_thumbnail_id, $size, $attr ) {
    // Single posts render the thumbnail at full content width.
    // Leave the default sizes value in place for those.
    if ( is_singular() ) {
        return $html;
    }

    $html = str_replace(
        'sizes="100vw"',
        'sizes="(max-width: 640px) 50vw, 300px"',
        $html
    );

    return $html;
}, 10, 5 );
Image payload on archive pages dropped from ~1,400 KiB to ~180 KiB per page load. On pages where the LCP element was a post thumbnail, LCP improved by another 0.3s - now sitting around 1.1s.
Close, but still over the SLO.
Dequeuing Dashicons and Deferring WonderPush: 85KB Off the Critical Path
Two assets were loading on every front-end page that had no business being there.
Dashicons. WordPress core enqueues the admin icon font for all visitors, logged in or not.
Logged-out users never see the admin bar. They have no use for an icon font.
The stylesheet alone is render-blocking.
php
<?php
/**
 * Dequeue Dashicons for unauthenticated front-end visitors.
 *
 * Priority 20 is intentional. Some plugins re-enqueue Dashicons as a
 * dependency at the default priority of 10. Running this dequeue at 10
 * removes the core registration, but those plugins add it back before
 * wp_print_styles() fires. At priority 20, we fire after them.
 *
 * First attempt at priority 10 did not work in production for this reason.
 */
add_action( 'wp_enqueue_scripts', function() {
    if ( ! is_user_logged_in() ) {
        wp_dequeue_style( 'dashicons' );
    }
}, 20 );
The priority note is not cosmetic. The first version of this snippet ran at priority 10 and Dashicons kept reappearing in production.
A contact form plugin was re-enqueuing it as a dependency after the dequeue fired. Raising to priority 20 resolves the race.
WonderPush. The push notification SDK was loading synchronously in <head>.
A browser does not need an active connection to a notification service before it can render an article. The SDK initialises its own async queue internally - deferring the loader script has no effect on notification delivery or subscription state.
The snippet targets wonderpush-loader specifically. If your WonderPush version uses a different handle, or you are adapting this for a different third-party script, find the correct handle first - otherwise the filter silently does nothing:
php
// Run this temporarily to log all registered script handles.
// Check your error log, then remove it.
add_action( 'wp_print_scripts', function() {
    error_log( implode( ', ', array_keys( wp_scripts()->registered ) ) );
});
Once you have confirmed the handle, use this to defer it:
php
<?php
/**
 * Defer WonderPush loader script.
 * Use defer, not async - WonderPush's internal sequencing can break
 * under async if the page has inline SDK initialization calls.
 *
 * @param string $tag    Full <script> HTML tag.
 * @param string $handle Registered script handle.
 * @param string $src    Script source URL.
 * @return string Tag with defer attribute added.
 */
add_filter( 'script_loader_tag', function( $tag, $handle, $src ) {
    if ( 'wonderpush-loader' === $handle ) {
        return str_replace( ' src=', ' defer src=', $tag );
    }
    return $tag;
}, 10, 3 );
Combined, these two changes removed approximately 85KB from the blocking critical path on every page load. Neither change on its own would move a PSI score dramatically.
Together, in combination with the jQuery and image fixes already in place, they brought the score to around 95.
Getting from 95 to 99 required one more thing.
font-display: swap in LiteSpeed Cache - How 1,480ms of Hidden LCP Disappeared
Inter was rendering invisible.
Not missing - invisible. Lighthouse flagged a 1,480ms text visibility delay and I did not understand what that meant until I recorded a load in Chrome DevTools and watched it happen: the layout was stable, the background was painted, the hero text block was sized and positioned correctly - and the characters simply were not there for a second and a half.
The browser had already laid out the page. It was just waiting for the font file before it would show the glyphs.
The reason is font-display: auto, which most browsers implement as block - hold text rendering for up to 3 seconds while the web font loads. If the font does not arrive in time, fall back to the system font.
The LCP clock does not stop until the element is fully visible. That 1.48 seconds was sitting on top of my LCP measurement the entire time, and every fix I made before this one was working around it without touching it.
font-display: swap changes the contract: render text in the system fallback immediately, swap to the web font when it loads. On a content site using Inter at standard body weights, the visual flash during the swap is imperceptible.
But the LCP timer now stops as soon as the layout is stable rather than waiting for the font file.
The fix did not require touching any theme files. In LiteSpeed Cache: Page Optimization > CSS Settings > Font Display, set to swap.
LiteSpeed injects the descriptor into every @font-face rule it processes, including those from themes and plugins it has no explicit configuration for.
LCP dropped from 1.1s to 0.8s. That was the change that put the LCP SLO in the green.
The Regression: LiteSpeed Cache's WooCommerce Preset Silently Re-enabled JS Combine
I went to sleep with a score of 96. I woke up to 74. Nothing had been deployed.
This is the part of the audit I think about most, because the failure mode had nothing to do with code. It had everything to do with a cache plugin that had opinions I did not know about.
What happened with TBT. LiteSpeed Cache v7.8.1 ships with a preset detection system. When it detects certain plugins activating, it applies a pre-configured optimization profile.
A dormant WooCommerce plugin on the site - installed for a planned future feature - had its options table initialized during a routine WordPress cron run. LiteSpeed's preset system detected WooCommerce and applied its WooCommerce profile, which re-enabled JS Combine.
TBT went from 0ms back to 460ms silently, with no visible change in the WordPress admin.
What happened with LCP. LiteSpeed's native lazy loading classifies images as above-fold or below-fold using a heuristic based on DOM position, not rendered viewport position. The hero image on the homepage is the third <img> element in DOM order - it comes after the site logo and an SVG icon in the nav.
LiteSpeed classified it as below-fold and applied loading="lazy".
loading="lazy" on the LCP element is one of the most damaging things you can do to LCP. The browser's preload scanner identifies LCP candidate images and begins fetching them at highest priority before layout is complete.
loading="lazy" tells the preload scanner to explicitly skip the image. The fetch does not begin until after the browser has completed layout, run intersection observer checks, and confirmed the element is in the viewport.
On the Lighthouse throttle profile, this added roughly 0.8s to LCP.
The fixes. JS Combine: disabled again. LiteSpeed Cache preset: locked to Custom to prevent automatic reapplication.
For the lazy load issue, I added the hero image container's CSS class to the Lazy Load Excludes list in LiteSpeed Cache > Page Optimization > Media Settings.
I want to be specific about the lazy load fix: I did not add loading="eager" to the image via WPCode. That attribute cannot undo the damage once LiteSpeed's optimization layer has already added loading="lazy" - the conflict resolution is undefined and varies by browser.
The correct fix is to tell LiteSpeed not to touch that element at all, using its own exclusion system.
Closing the Gap: From 95 to 99
I want to be honest about this section. Getting from 95 to 99 is not a repeatable recipe.
At 95, you have fixed every obvious thing. What remains is specific to your stack, your theme, your third-party scripts, and the particular way Lighthouse happened to run on your page that day.
The gap between 95 and 99 on a different site might close with completely different changes - or might not close at all without a significant architectural change.
Here is what I did on studyinfo.net. Take these as observations, not instructions.
LCP image preload. I added a <link rel="preload" as="image" fetchpriority="high"> hint for the homepage hero image via LiteSpeed Cache's preload settings. The idea is to push the fetch ahead of where the preload scanner would naturally discover it.
On this site it moved LCP by approximately 120ms on warm cache loads. On other sites I have tested this on, it moved nothing measurable.
It depends entirely on what else is competing for network priority at the same moment.
DNS prefetch for third-party origins. WonderPush, Google Fonts fallback, and Cloudflare Web Analytics each need a DNS resolution before their first connection. LiteSpeed Cache detects third-party origins in page output and injects <link rel="dns-prefetch"> hints automatically.
Each lookup saved is 20-40ms. Three of them is not nothing, but it is also not the reason this site reached 99.
Redis object cache. Hostinger's LiteSpeed tier includes Redis. Enabling it routes repeated database queries - menus, widgets, options - to memory instead of MySQL.
This does not show up in Lighthouse lab scores at all, because Lighthouse uses a synthetic origin with a fixed simulated TTFB. But it does affect the CrUX field data that Google uses for actual ranking signals, where real-user TTFB variance across thousands of visits matters.
I enabled it. I cannot tell you exactly how much it contributed to the score because Lighthouse cannot see it.
The honest answer is that 95 to 99 on this specific site came from the combination of all three, against a relatively clean plugin footprint with no page builder and only a handful of third-party scripts. If your site runs Elementor, WooCommerce, or carries a dozen external dependencies, 95 might be your realistic ceiling without more significant changes.
95 passes every Core Web Vitals threshold that affects ranking.
What the Final State Looks Like
| Metric | Before | After | SLO | Status |
|---|---|---|---|---|
| Performance | 78 | 99 | 99+ | Met |
| Accessibility | 94 | 100 | 100 | Met |
| Best Practices | 92 | 100 | 100 | Met |
| SEO | 96 | 100 | 100 | Met |
| FCP (desktop) | 1.2s | 0.4s | < 0.8s | Met |
| LCP (desktop) | 2.4s | 0.8s | < 1.0s | Met |
| TBT (desktop) | 460ms | 0ms | 0ms | Met |
| CLS | 0.14 | 0.054 | < 0.1 | Met |
| Speed Index | 4.1s | 2.5s | < 3.0s | Met |
CLS landed at 0.054, not zero. The residual shift comes from the WonderPush notification banner - it injects into the DOM about 1.2 seconds after load, after the layout stability window has started. The banner is position: fixed so it does not move in-flow content, but Chromium's CLS algorithm counts viewport-relative anchor shifts, and the banner triggers one. The correct fix is a zero-height DOM placeholder that expands when the banner appears, but WonderPush does not expose that control. 0.054 is the floor with push notifications enabled. It passes the Good threshold (< 0.1).
No new infrastructure. No additional spend. Two PHP snippets under 40 lines total. Every other change was a configuration choice in LiteSpeed Cache v7.8.1.
The score of 99 is reproducible. I have run PSI on the homepage six times since the audit completed. The median is 99. It is not a timing artifact.
Three things from this audit I will not forget.
First: LiteSpeed Cache has opinions, and it will act on them without asking. The preset system, the lazy load heuristic, the WooCommerce detection - these are not bugs. They are defaults built for the median site. If your site is not the median, you have to tell it explicitly. Lock the preset to Custom. Add your exclusions. Check after every plugin activation.
Second: JS Combine is the most confidently wrong advice in WordPress performance circles. It made sense in 2014. On HTTP/3 in 2026 it actively damages TBT by handing V8 a monolithic input and destroying streaming compilation. The fact that it is still a recommended setting in half the guides I have read while writing this is a problem.
Third: a score of 95 that you understand is worth more than a score of 99 that you cannot explain. When this site regressed to 74, I knew exactly where to look because I had changed one thing at a time and logged each result. That is the only reason the recovery took twenty minutes instead of a day.
If you are on LiteSpeed and sitting in the 80s: disable JS Combine first. Measure TBT before and after. Everything else is secondary to that one change.
Keep Reading
K
Kiro vs Cursor vs Windsurf vs Claude Code vs Codex vs Antigravity: What I Actually Use as an SRE
40 min read
AIDev Tools
How to Build a URL Shortener on AWS in 2026: The Complete End-to-End Guide
39 min read
AWSServerless
How I Made My Next.js Portfolio Actually Production-Ready (For $0)
15 min read
Next.jsDevOps
Subscribe to Newsletter
Get the latest posts delivered right to your inbox
Join 1,000+ readers. No spam, unsubscribe anytime.